UC Berkeley's CUA-Lite runs OSWorld-style computer-use agent tasks in Docker, no VM needed
Published by AINave Editorial
If you have tried to benchmark or train a computer-use agent, you have hit the fragmentation problem: agents in one repo, environments in another, traces in a third, and no shared interface between them. UC Berkeley's CUA-Lite is an open platform that puts all four pieces behind a single action space and data schema across desktop, browser, and mobile. The most immediately useful part: it reproduces OSWorld benchmarks inside a Docker container, no VM required.
What CUA-Lite does differently
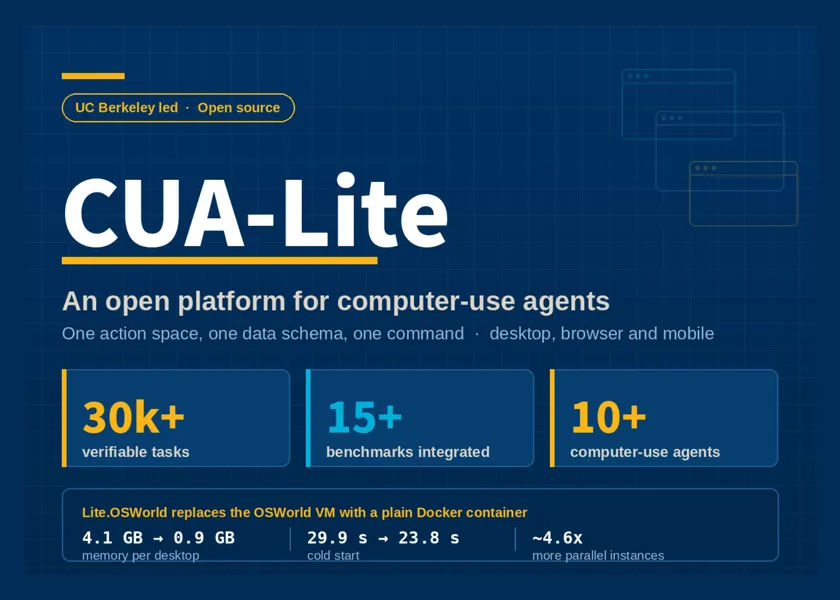
CUA-Lite consolidates agents, environments, traces, and evaluators into one stack. The team's core argument is infrastructural: currently each component lives in separate repositories with incompatible interfaces. CUA-Lite defines one action space per platform (desktop, browser, mobile), one data schema (LiteSample, parquet plus images), and one command to run everything. The stack installs with uv sync --all-extras on Python 3.12 and runs on any Docker host without /dev/kvm, so cloud instances, CI runners, and nested containers all work.
Lite.OSWorld: OSWorld tasks without a VM
The most concrete contribution is Lite.OSWorld. The original OSWorld provides a faithful Ubuntu desktop but ships as a full QEMU/KVM virtual machine per task, requiring nested virtualization that most managed infrastructure does not expose. CUA-Lite reproduces the same task suite and evaluators on a GNOME desktop inside a plain Docker container. The obvious concern is fidelity, and the team addresses it directly: across 13 models, Lite.OSWorld scores match the OSWorld VM's scores, so a training signal earned in the container transfers back to the real benchmark.
Beyond OSWorld, the platform includes Lite.ScaleCUA, Lite.CUAGym, and Lite.CUAWorld, the last expanding into roughly 40 applications including Blender, QGIS, and VS Code, totaling 30k+ verifiable tasks.
A unified data and training stack
CUA-Lite's second layer is LiteSample, a single supervised-learning schema shared across every environment, agent, and task type. Ten-plus existing CUA datasets have been preprocessed into LiteSample and published free on Hugging Face, including Aguvis, OpenCUA, ScaleCUA, GUI-360, GUIOdyssey, and Multimodal-Mind2Web. Alongside those sit fresh rollout datasets generated by a frontier teacher model running through the sandboxes, meant for distillation into smaller students. Because model families expect different scaffolding, the framework ships per-model adapters that pack a unified LiteSample into each model's training format, including history collapsing so several steps share one forward pass.
Agents and environments meet in lite.gym: screenshots up, actions down, with one action space per platform. Ten-plus agents are built in (GPT, Claude, Gemini, Qwen3-VL, UI-TARS, Fara-7B, MAI-UI) and 15+ benchmarks are integrated, spanning grounding (ScreenSpot-Pro), desktop (OSWorld, WindowsAgentArena), browser (WebArena, VisualWebArena, MiniWoB), and mobile (AndroidWorld, MobileGym). Swapping --model-id and --env-id in scripts/rollout.py is the whole interface.
The same loop serves training. For SFT, the README documents fine-tuning Qwen3-VL-2B-Instruct on Lite.ScaleCUA desktop trajectories, lifting mean episode return from 0.138 to 0.237 on a 332-task lite.osworld eval split, using two GPUs. For RL, rollouts scored in the environment drive GRPO updates on top of Slime, with a worked MobileGym example covering 416 mobile tasks across 28 apps.
What this means for AI builders
If you are building or evaluating computer-use agents, CUA-Lite lowers the barrier to reproducible benchmarking and training. You can run OSWorld tasks in Docker on any cloud instance or CI runner, without needing nested virtualization. The shared LiteSample schema and per-model adapters mean you can train on the same data format across different model families without writing custom data pipelines. The integrated agent and benchmark library means you can compare GPT-4o, Claude, Qwen3-VL, and a fine-tuned 2B model with one command.
Caveats to keep in mind
The fidelity claim (matching scores across 13 models) is the team's own reported result, not independently verified. The SFT improvement from 0.138 to 0.237 is a single configuration on two GPUs, not a reproduced result. Container vs. VM fidelity may vary for tasks outside the tested set. The 30k+ task count is a platform claim, not independently audited. For production use, you will still need to validate that container-based training signals transfer to your target deployment environment.
FAQs
uv sync --all-extras on Python 3.12 and use scripts/rollout.py --model-id <model> --env-id lite.osworld. Setup instructions.Sources
- UC Berkeley Researchers Release CUA-Lite, an Open Platform Unifying Sandboxes, Data, Evaluation and RL for Computer-Use Agents
- OpenAI Releases GPT-6 Astra: A 1.05M-Context Computer-Use Model Gated Behind a 'Critical' Cyber Threshold - MarkTechPost
- Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks for Long-Horizon Legal Agent Work - MarkTechPost
- Anthropic Released Claude Commerce Agents: An Apache-2.0 Blueprint for Shopping and Merchant Agents Across Retail, Travel, Telecom and Entertainment - MarkTechPost
- Cua: Scale computer fleets for computer-use agents