NVIDIA Opens NVLink Fusion to Rival Accelerators: AI Infrastructure as a Toll Road
Published by AINave Editorial • Reviewed by Ramit
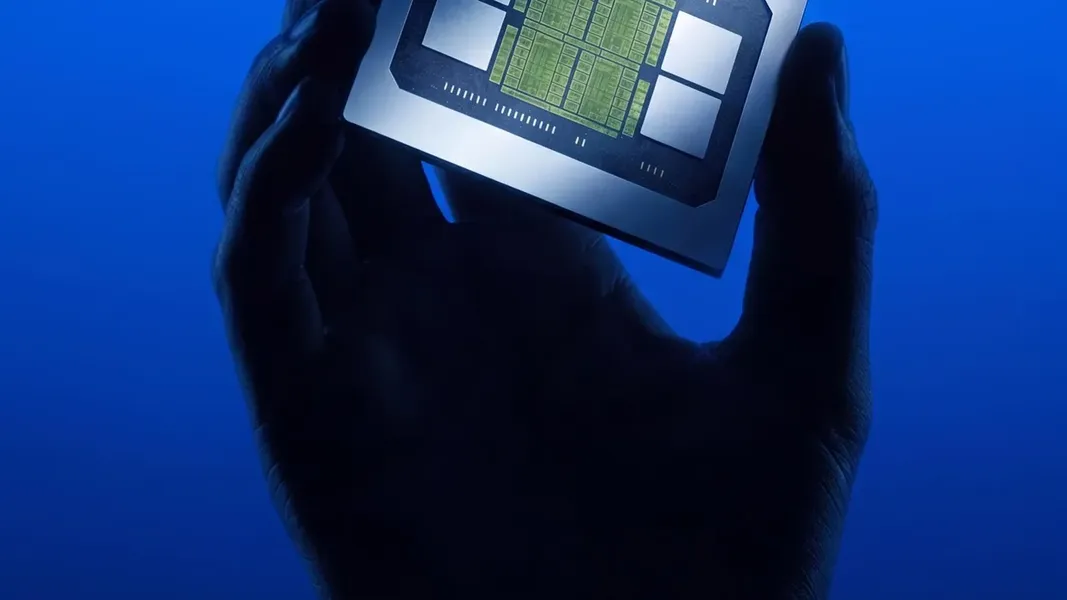
NVIDIA is opening part of its data-center ecosystem to rival chipmakers. D-Matrix, a Microsoft-backed inference startup valued around $2 billion, will plug its Raptor processors into NVIDIA-powered racks via NVLink Fusion. The first rack-scale products are expected in 2027, with Raptor tape-out near the end of 2026.
NVLink is the high-speed interconnect that lets racks of GPUs work as a single computer. NVLink Fusion extends that fabric to selected partners, letting their silicon share memory bandwidth and communicate with NVIDIA GPUs and CPUs using a common interface. For d-Matrix, this connection is critical: inference accelerators live or die on how fast they can reach model weights and shuttle tokens to a host system.
Why NVIDIA is inviting competitors into its own racks
On the surface, helping a competing accelerator slot into your rack looks like a concession. The logic becomes clearer when you follow the money through the full stack. NVIDIA is positioning itself as the toll collector for AI data centers rather than trying to win every chip sale inside them.
Even when a partner supplies the principal accelerator, NVIDIA keeps collecting from networking, CPUs, NVLink switches, BlueField storage, and CUDA software. CEO Jensen Huang framed the strategy bluntly: "AI has reached its inflection point. It's doing useful work. Its tokens are productive and profitable. Now, compute is revenue."
The numbers reinforce the point. NVIDIA reported total revenue of $96.22 billion, up 105.8% year over year, and guided the current quarter to $108.0 billion. Data-center networking alone brought in $40.31 billion, up 138% year over year. NVIDIA pegs data-center revenue per gigawatt at roughly $18 billion for Hopper, $25 billion for Blackwell, and $40 billion for Vera Rubin, illustrating how the AI factory now includes far more than GPUs.
What changes for AI builders
The shift matters for anyone provisioning inference infrastructure or building on NVIDIA’s ecosystem. NVLink Fusion is turning the proprietary interconnect into a broader platform standard, and that changes the competitive dynamics of AI hardware.
Third-party accelerators from d-Matrix, Groq, and Marvell gain a credible on-ramp into workloads where NVIDIA’s GPU margins are highest. Inference is the part of the stack where custom silicon competes best on cost and power per token. If Raptor or similar parts prove several times more efficient per token, hyperscalers could shift the highest-volume workloads off NVIDIA GPUs while keeping the fabric. NVIDIA would still collect a toll, but a smaller one per rack.
For AI builders, this means more accelerator choice in the same rack ecosystem, but also a reminder that platform lock-in at the interconnect layer may outlast chip cycles. The accelerator that wins on efficiency today could be swapped next year; the fabric standard that ties the rack together is stickier.
Partners and integration timeline
D-Matrix is not NVIDIA’s only NVLink Fusion partner. Marvell joined earlier this year, and Groq is being integrated at the rack level, with the CFO calling out a "strategic partnership with Marvell via NVLink Fusion" in the most recent quarter. Financial terms of the d-Matrix arrangement have not been disclosed.
Caveats and risks
Several important uncertainties remain. NVIDIA has not disclosed the financial terms of the d-Matrix arrangement, and the tape-out timeline for Raptor is forward-looking. Rack-scale products depend on successful tape-out and market adoption. There is a real risk that NVLink Fusion becomes the standard, third-party accelerators capture inference share, and NVIDIA’s per-rack dollar content stops climbing. Management expects gross margins to bottom in the 71% to 72% range before recovering, a signal that lower-margin inference workloads may already be growing faster than high-margin training.
What to watch next
The durable question is whether NVIDIA earns more as the platform owner than it would trying to win every chip sale. The NVLink Fusion strategy suggests NVIDIA is betting that the fabric, networking, and software are the defensible layers. For AI builders, the practical takeaway is that hardware procurement decisions may need to account for interconnect compatibility, not just raw chip performance. The accelerator that works best in your rack today might not be the one that works best next year, but the fabric around it will probably be NVIDIA’s.
FAQs
Sources
- Nvidia Just Invited a Rival Chipmaker Into Its Own Racks. Here's Why
- Nvidia invests $2B in Marvell, a rival chipmaker | LinkedIn
- Nvidia vs. Micron: Which Is the Better Artificial Intelligence... - AOL
- Nvidia Will Invest $5 Billion In Rival Chipmaker Intel, Following $10...
- Nvidia to join Dow Jones Industrial Average, replacing rival...
- Nvidia's Hugging Face Acquisition Is Logical, Ambitious, and Headed Straight...
- CES 2026: AMD says 'You ain't seen nothing yet' on AI
- Nvidia’s Biggest AI Bet Just BACKFIRED - YouTube
- Nvidia's $12.9B Hugging Face Deal Sparks Bias Fears [2026]
- Why Nvidia’s Chip Rivals Have Left It in the Dust This... - Barron's
- Nvidia to join Dow Jones Industrial Average, replacing rival...
- To Compete With New Rivals, Chipmaker Nvidia Shares Its... | WIRED
- Nvidia Just Invited a Rival Chipmaker Into Its Own Racks. Here’s Why