ICML 2026 in Seoul: Record Submissions, Agentic AI Focus, and a Peer-Review Integrity Crackdown
Published by AINave Editorial
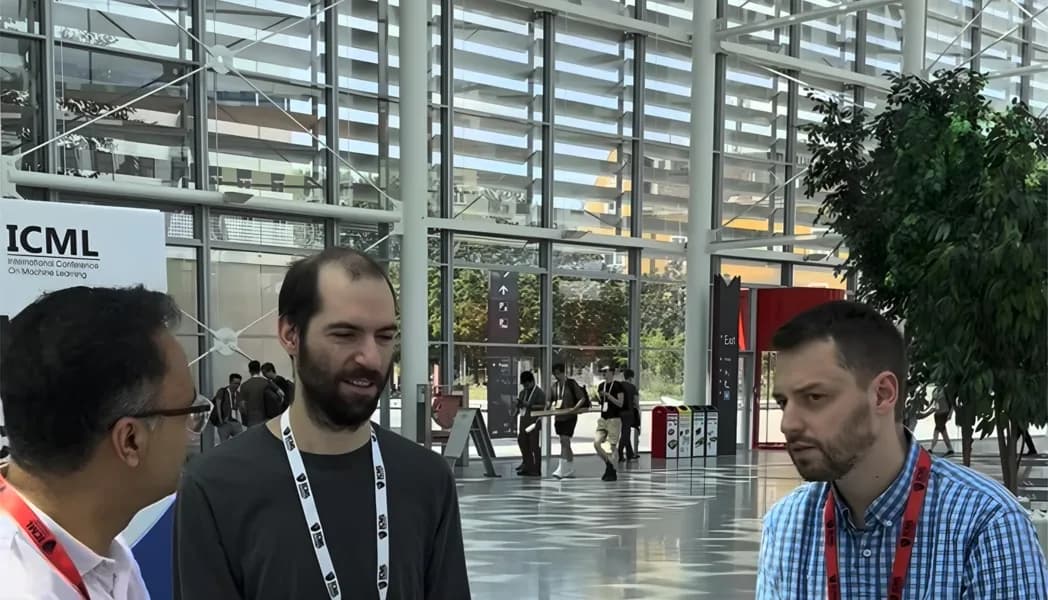
ICML 2026, the International Conference on Machine Learning, opened on July 6 in Seoul, South Korea, at the COEX Convention & Exhibition Center. The conference runs through July 11, bringing together over 11,000 researchers Source. It arrives with a record number of submissions, a new policy on LLM use in peer review, and a research program heavily weighted toward agentic AI and safety. The conference also coincides with the inaugural UN Global Dialogue on AI Governance in Geneva, highlighting the tension between rapid AI research and slow-moving governance Source.
What happened
ICML 2026 received 23,918 submissions, more than double the previous year's record of 12,107 Source. The program chairs accepted 6,352 papers, a 26.6% acceptance rate. Of those, 536 papers received Spotlight designations (2.2% of submissions), and 168 were selected for Oral presentations (the top 0.7%) Source.
Peer-Review Integrity: The LLM Detection Experiment
The most significant institutional story of ICML 2026 is its enforcement of a new LLM policy for reviewers. The conference implemented a two-track system: Policy A prohibited all LLM use in review writing, while Policy B permitted limited assistance such as understanding a paper or polishing prose, but not judging quality or drafting the review Source.
To detect violations, the program committee used a technique based on recent research published in PLOS ONE. They created a dictionary of 170,000 phrases and randomly selected two for each submitted paper. Invisible, machine-readable instructions were embedded in each PDF, telling any LLM processing the document to include both phrases in the generated review. The probability of a random coincidence was less than one in ten billion Source.
The results: 795 reviews (about 1% of all submissions) were flagged as LLM-generated from Policy A reviewers. This affected 506 unique reviewers. Of those, 398 were reciprocal reviewers whose own submissions depended on their review work; their papers were desk-rejected, totaling 497 papers (roughly 2% of all submissions) Source.
The organizers acknowledged the method's limits. Inserting hidden prompts "is not a difficult measure to circumvent," they wrote on the ICML blog, "particularly if it is known publicly." The method only catches reviewers who feed the entire PDF to an LLM and copy-paste the output. Paraphrasing, partial drafts, or working around the injected prompt would not be detected Source. NeurIPS, which holds its conference in Sydney in December 2026, has independently adopted a similar approach Source.
Agentic AI Dominates the Workshop Program
The clearest signal about research direction came from the workshop proposals. Workshop chairs noted that "agentic AI" appeared in no fewer than 60 of the 247 workshop proposals received Source. The final program accepted 44 workshops, plus 4 affinity workshops. Agentic AI refers to systems that pursue goals through autonomous loops: receiving an objective, selecting actions, calling tools or APIs, observing results, and iterating without step-by-step human approval.
Among the accepted workshops directly addressing agentic AI are "Agents in the Wild" (focused on safety, security, and multi-agent coordination), "Statistical Frameworks for Uncertainty in Agentic Systems," and "Technical AI Governance Research" Source.
Why AI builders should care
For teams shipping AI products or building developer tools, ICML 2026 crystallizes three practical dynamics.
First, the peer-review enforcement experiment provides a real-world case study in LLM misuse detection. If 1% of reviewers were caught by a method that catches only the most careless users, the actual rate of LLM use in reviews is likely substantially higher. Those building tools for AI-assisted writing, code review, or content generation should watch how conferences like NeurIPS and ICML evolve their policies. The detection method itself is a prompt-injection attack in a new context and suggests that watermarking and hidden instructions are viable for some use cases.
Second, the dominance of agentic AI in workshop proposals means safety, evaluation, and uncertainty quantification for autonomous agents are now core research problems, not side conversations. The technical research problems most relevant to builders include constrained policy optimization, uncertainty quantification for multi-step decisions, and conformal prediction guarantees for agent pipelines. Papers such as "Do We Need Adam?" (which found SGD matches or outperforms AdamW during RL fine-tuning while updating fewer than 0.02% of parameters) have direct engineering implications for memory-efficient LLM training Source.
Third, the alignment track covers work on steerable AI values (e.g., the paper "VALUEFLOW: Toward Pluralistic and Steerable Value-based Alignment"). For builders deploying agents, this research is directly relevant to controlling model behavior in production Source.
Caveats
Conference press coverage and secondary reporting provide the details here, and some interpretations may evolve as more papers and workshop recordings become available. The detection method's limits mean the 1% flag rate is a floor estimate, not a ceiling. The policy experiment at ICML 2026 is a first step, and its effectiveness for future conferences is uncertain. In-person registration sold out, but workshop and virtual registration remain available Source.
Sources
- ICML 2026 Opens Monday in Seoul: Agentic AI Tops Record Year as Peer Review Strains
- 2026 Conference
- Together AI Showcases Nine Papers at ICML 2026 in Seoul
- ICML 2026 | Centific
- Tadepalli researcher to present AI paper at prestigious ICML 2026...
- ICML 2026 Opens in Seoul Next Week: Record 23,918 Submissions Signal AI Agent Safety Era
- Ronit Chaodhary, who is a 21-year-old NST student, publishes AI for science paper accepted at ICML 2026 workshop
- International Conference on Machine Learning (ICML) 2026
- ICML Night - Instruct.KR X Exa AI Search Technology... | Event Match
- MCMC Flags 345,712 Harmful Posts, Eyes Agentic AI To Fast-Track...
- Together AI at ICML 2026: frontier research across the full stack